Dual-channel recording
Captures system audio and your microphone at the same time and mixes them automatically. Online calls, lectures, interviews and in-person discussions — you never miss either side.
 VoxMinutes
Records your system audio and microphone together, turns speech into text as it happens, translates live into 13 languages and writes your AI meeting notes in one click. Everything runs on your own computer — free and open source, forever. Switch to cloud models whenever you want more power.
New users get 100 credits free (about 3 hours of meetings)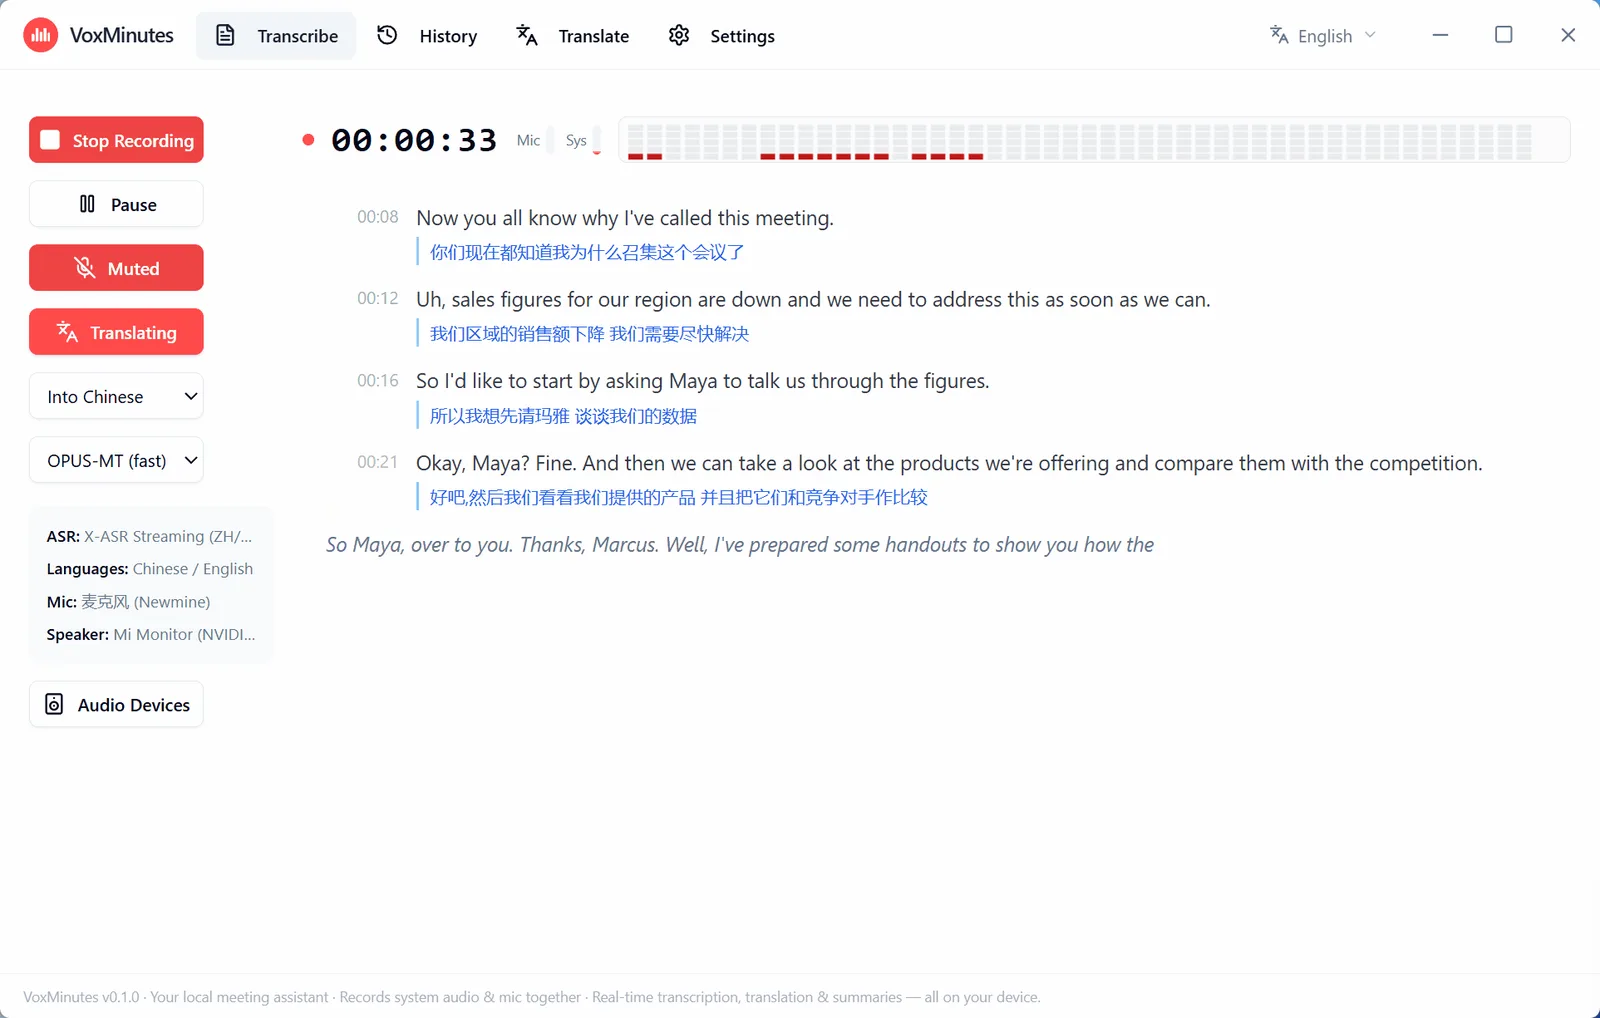
One recording produces the transcript, the translation, the subtitles and the notes — all on your own machine.
Captures system audio and your microphone at the same time and mixes them automatically. Online calls, lectures, interviews and in-person discussions — you never miss either side.
Two on-device engines — X-ASR and SenseVoice — stream text out as people speak, entirely offline.
A sentence-by-sentence pipeline into 13 target languages, with each translation sitting right under the original line.
A local LLM writes up the topics, decisions and action items offline — or point it at your own API.
A separate subtitle window that stays on top, moves where you drag it and lets you set the line count and font size. Watch a foreign-language meeting like a subtitled film.
Play back the original transcript or the translation in 31 languages, with a choice of voices.
Every meeting lives in a local SQLite database with full-text search, inline editing and re-recognition using a different model.
TXT / SRT / Markdown / meeting notes in one click — and print straight to PDF for your archive.
Cloud models wired into the app, subtitles lifted onto your desktop, and free finally kept apart from paid.
No more waiting on multi-gigabyte downloads. Call cloud models directly for stronger multilingual recognition, more accurate live translation and larger summarisation models — pick one and go. You can re-run the same meeting through a different model and compare.
An independent subtitle overlay that always stays on top, moves where you want it, and lets you set the number of lines and the font size. Live subtitles floating over any meeting, stream or lecture.
Local models are free forever, with no limits on time or number of runs. Credits are only spent when you deliberately choose a cloud model, billed by real usage — no subscription, no monthly plan, no auto-renewal. Purchased credits never expire.
One app, two engines. Use local for everyday meetings, switch to cloud for accuracy or more languages. You can change your mind at any time.
| Local models | Cloud models | |
|---|---|---|
| Cost | Free forever, unlimited time and runs | Credits deducted by actual usage |
| Network | Fully offline once models are downloaded | Needs a connection — direct from most regions |
| Privacy | Audio and text never leave your computer | Only the content you choose is sent to the server |
| Setup | One-time 0.5–2.5 GB model download | Nothing to download — pick one and go |
| Best for | Everyday meetings, privacy-sensitive work, offline use | Multilingual meetings, long sessions, maximum accuracy |
Credits are only spent on cloud models — speech recognition, live translation, meeting summaries and read-aloud all share one balance. Codes are issued automatically after payment; paste yours in the app under Account → Top up / Redeem.
Try the cloud models out
Better value for long or multilingual meetings
Lowest cost per credit
Enough for about 3 hours of full meetings (recognition + translation + summary). Limited launch offer; gifted credits are valid for 90 days from the day they are claimed.
Hours are estimated for a typical 1-hour meeting running speech recognition + live translation + meeting summary. Actual usage depends on the models you choose.
No command line, no environment setup — install it and follow the wizard.
Grab the installer for your platform (about 50 MB) from GitHub Releases and run it. See the FAQ below for first-launch security prompts.
The first-run wizard downloads or imports local models, with automatic mirror fallback — or pick a cloud model and skip the download entirely.
Choose your microphone and system audio, then hit record. Text appears live; turn on translation, desktop subtitles and read-aloud whenever you like.
Generate AI meeting notes in one click. Search, edit and re-recognise from history, then export TXT / SRT / Markdown / PDF.
The core app is completely free and open source (AGPL-3.0). Local transcription, translation, meeting summaries and desktop subtitles have no time or usage limits, and no account is required.
Credits are only spent when you deliberately choose a cloud model — billed by actual usage, with no subscription, no monthly plan and no auto-renewal. New users also get 100 free credits to try it out.
With local models, once the models are downloaded the app works fully offline. Audio, transcripts, translations and summaries are produced on your own computer and never leave it.
Only when you deliberately pick a cloud model is the relevant audio or text sent to a server. Local features are unaffected either way.
No. Every model is quantised and runs on CPU alone; 8 threads or more is recommended. Local live transcription runs at roughly RTF 0.25, and local live translation takes about 2–4 seconds per sentence.
Windows 10 / 11 and macOS (Apple silicon) are both fully supported, with installers around 50 MB. Linux is planned — vote on GitHub Issues to help us prioritise.
It captures audio at the system level rather than hooking into one specific app, so Zoom, Teams, Google Meet, Feishu, webinars, lectures, streams and podcasts all work — and so does walking into a room and recording a face-to-face discussion.
The installers are not code-signed yet, so your system will stop you once — that does not mean anything is wrong. The source is fully public, and you can also build it yourself following the README.
Windows: when SmartScreen shows a blue warning, click More info → Run anyway.
macOS: if it says the developer cannot be verified, right-click the app and choose Open, or allow it under System Settings → Privacy & Security.
The cloud side includes Doubao, Qwen, MiMo and Deepgram, covering 30+ languages. Doubao is strong for Chinese, Deepgram for English and overseas use, and Qwen for mixed-language meetings.
You can re-run the same meeting through a different model and compare the results, then keep whichever you prefer.
A typical 1-hour meeting that runs recognition + translation + summary costs roughly 34 credits, so 100 credits is about 3 hours of full meetings. Plain file transcription goes considerably further.
Actual usage depends on the models you pick, and every transaction is itemised in the app under Account.
Buy a credit pack on this page and the redemption code appears automatically once payment completes. Open VoxMinutes → Account → Top up / Redeem, paste the code, and the credits land instantly.
Your balance is tied to your account, so switching computers or reinstalling will not lose it. Purchased credits never expire.
Free download. Local models are fetched by the wizard, with automatic mirror fallback — no proxy needed.
If macOS says the developer cannot be verified on first launch, right-click the app and choose Open, or allow it under System Settings → Privacy & Security.